For a long time, I thought backup integrity mostly took care of itself once the datastore looked healthy.
Jobs were succeeding.
Retention looked sensible.
Space graphs were moving.
Nothing seemed obviously wrong.
That was the comforting version of the story.
The more honest version is that old backups do not remain trustworthy merely because nobody touched them. Proxmox Backup Server’s own maintenance documentation says this plainly: even a previously successful verification should not be treated as permanent confidence, because physical drives are susceptible to damage over time and old working backups can become corrupted through bit rot/data degradation.
That sentence changed the whole tone of backup maintenance for me.
It meant verify, prune, and garbage collection were not just housekeeping tasks.
They were the difference between owning backups and continuing to trust them.
- Why backup integrity in PBS needs active maintenance, not only successful jobs
- What verify jobs actually check and why PBS recommends reverification
- What pruning removes and what it deliberately does not remove
- How garbage collection completes the cleanup after pruning
- What kind of recurring maintenance rhythm I think feels healthiest in a homelab
For the technical baseline below, I use Proxmox Backup Server documentation and separate documented platform behavior from my own placement and operating recommendations.
Verify jobs are PBS’s way of turning trust into a routine
The official PBS maintenance guide describes verification as a datastore maintenance task designed to ensure that backup data is intact. Verification is generally carried out through scheduled verify jobs, and PBS lets you control whether already verified snapshots are ignored and how long a successful verification remains fresh before the snapshot is considered outdated again.
That is a very healthy design.
It means the system is not assuming that one good verification result should live forever.
It assumes trust expires.
PBS also exposes this through the CLI. The documentation shows a manual verification command like:
proxmox-backup-manager verify <datastore> \
  --read-threads 1 \
  --verify-threads 4 \
  --ignore-verified false
And the command syntax documentation shows that verify jobs can be created with options like:
--ignore-verified--outdated-after--read-threads--verify-threads- namespace scope controls such as
--nsand--max-depth
That matters because verify is not just a yes/no task.
It is a policy.
PBS explicitly recommends monthly reverification because storage ages
This is the most important line in the official docs for this whole topic.
PBS recommends reverifying all backups at least monthly, even if a previous verification succeeded. The reason they give is direct and concrete: physical drives are susceptible to damage over time, and an old working backup can become corrupted through bit rot/data degradation.
That is not my interpretation.
That is the official recommendation.
The docs then go one step further and suggest a two-layer rhythm:
- a recurring hourly or daily verification job that checks new and expired backups;
- another weekly or monthly job that reverifies everything.
I really like that structure because it reflects the real shape of trust:
- new backups need quick feedback;
- old backups need periodic revalidation;
- confidence should refresh on purpose, not by accident.
This is also where I think the phrase “automated bitrot checks” becomes fair, but with one nuance: PBS is not claiming magical immunity from every storage failure mode. What it is doing is automating regular integrity verification specifically because stored data can decay over time. That is the part I would emphasize.
Pruning and verification solve different problems
This is the distinction that keeps PBS maintenance from becoming muddy.
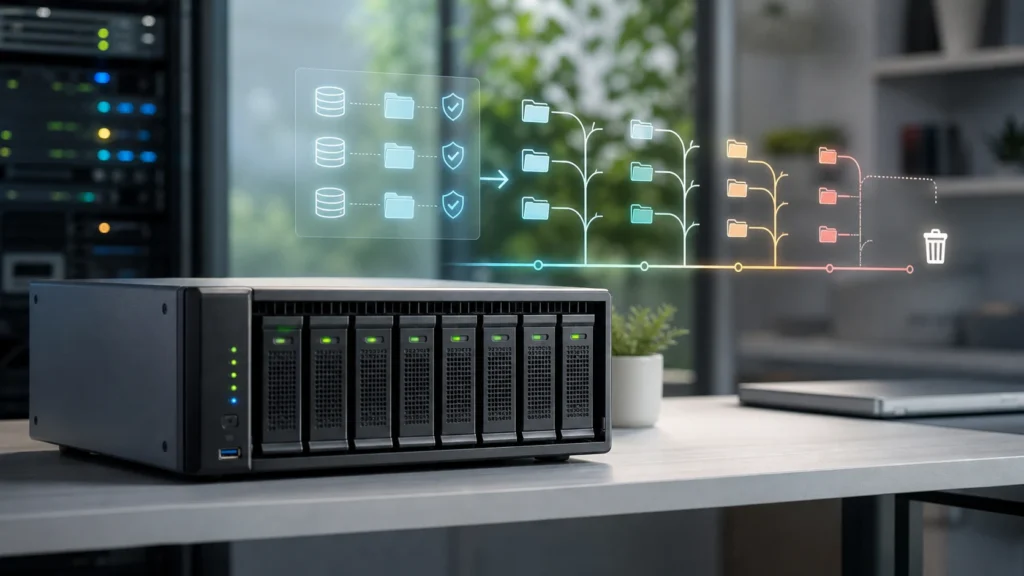
The PBS maintenance documentation defines pruning very clearly: pruning decides which backup snapshots should be kept and removes the rest. But when a snapshot is pruned, only the snapshot metadata is removed at that stage: manifest, indices, blobs, logs, and notes. The actual data chunks remain until garbage collection later determines that they are no longer referenced.
That means prune is about history policy.
Verify is about integrity policy.
They are related because both affect trust, but they do not solve the same problem.
Verification answers:
- is the backup data still intact;
- does the checksum-backed content still match expectations;
- should I keep believing this snapshot is recoverable.
Pruning answers:
- how much snapshot history do I want to keep;
- how aggressively do I roll older restore points out of the retention window;
- what backup generations are still part of the story.
That separation matters a lot in practice because it stops people from confusing “we kept many copies” with “we kept trustworthy copies.”
Prune does not instantly erase the underlying data
This is one of the most useful conceptual clarifications in PBS.
When pruning removes a snapshot, PBS does not immediately delete the underlying chunks of backup data. The official docs explain why: chunks may still be referenced by other backups, deduplication means multiple snapshots can share the same stored chunks, and locking the whole datastore to recalculate everything on every deletion would be too expensive and disruptive.
So PBS splits the work:
- prune removes snapshot metadata according to retention policy;
- garbage collection later reclaims unreferenced chunks.
That is elegant.
It is also something people need to understand clearly.
If space did not come back right after a prune job, that does not mean pruning failed.
It means the datastore is behaving exactly as PBS designed it to behave.
Garbage collection is what turns retention policy into reclaimed space
The official PBS maintenance guide describes garbage collection as the process that frees space in a datastore by deleting unused backup chunks. It explicitly says GC completes the pruning of backup snapshots, because pruning alone does not remove the underlying data.
The documentation also explains the GC process in two phases:
- mark: read index files and update access times for referenced chunks;
- sweep: iterate through chunks and delete those older than the cutoff and no longer referenced.
That explanation is one of the best pieces of PBS documentation because it makes the cleanup model readable instead of mystical.
PBS also recommends scheduling GC periodically, and says that for most setups a weekly interval is a good place to start.
That gives us a very practical division of labor:
- verify jobs maintain trust in the chunks you still care about;
- prune jobs decide which snapshot timeline should remain;
- GC eventually converts that policy into freed space.
Sensitive data and pruning deserve more respect than people often give them
The prune section of the official docs is careful here, and I think that caution is worth repeating.
PBS explicitly warns that sensitive information in a chunk can outlive a pruned snapshot as long as the chunk is still referenced elsewhere, and even when no snapshot references a chunk anymore, the chunk remains until garbage collection removes it after the grace-period logic.
That is a very important operational truth.
If the problem is not only “save space” but also “remove data that should no longer remain in the backup set,” then prune alone is not the whole answer. PBS says you may need to prune the relevant snapshots and then run garbage collection, with extra care in certain file-backup change-detection modes.
This is exactly the kind of detail that makes PBS feel adult to me. It refuses to pretend that deletion policy and storage reality are the same event.
A healthy homelab rhythm is usually layered, not dramatic
If I were describing the PBS maintenance rhythm I trust most now, it would look something like this:
- Backup jobs run on their normal schedule.
- A frequent verify job checks newly created and expired snapshots.
- A slower recurring verify job reverifies everything at least monthly.
- Prune jobs apply retention policy automatically.
- Garbage collection runs on a periodic schedule, often weekly to start.
- Restore drills still happen separately, because integrity verification is not the same thing as practical recovery rehearsal.
That last point matters a lot.
Verify jobs are essential, but they are still not a substitute for the kind of restore practice described in a real PBS restore drill. Verification tells you the stored data still matches its recorded integrity information. A restore drill tells you whether the human and operational recovery path still feels believable.
Both matter.
The most useful thing verify jobs changed for me was emotional honesty
Before I really understood PBS verification, I think I borrowed too much confidence from the existence of backups themselves.
Afterward, the story became more exact:
- some backups are recent and unverified;
- some are recently verified and feel warmer;
- some are older and need reverification;
- some should be pruned;
- some chunks will remain until GC catches up;
- trust is maintained, not declared.
That is a much better mental model.
It is also why this whole subject connects so naturally to the day PBS became real infrastructure and to file-level or full-guest recovery planning. Backup maturity is rarely one feature. It is a set of maintenance habits that make the stored copies feel increasingly real.
If those three jobs are blended mentally into one vague “cleanup” process, it becomes much harder to reason about why space has not returned yet, why old backups still need attention, or why a large retention window can still hide integrity risk.
Conclusion
Verifying backup integrity in PBS becomes much easier to understand once the maintenance model is separated cleanly. Verify jobs keep checking that backup data is intact. Proxmox explicitly recommends reverifying everything at least monthly because physical media can suffer bit rot/data degradation over time. Prune jobs decide which snapshots remain part of the restore history. Garbage collection later reclaims the unreferenced chunks those old snapshots left behind. Once those three jobs become one deliberate rhythm instead of three unrelated buttons, PBS starts to feel much more trustworthy.
FAQ
Does PBS really recommend reverifying backups even after a successful verify run?
Yes. The official maintenance documentation recommends reverifying all backups at least monthly because physical drives can degrade over time and old working backups can become corrupted through bit rot/data degradation.
Is pruning the same thing as deleting backup data?
Not immediately. PBS pruning removes snapshot metadata first. The underlying unreferenced chunks are reclaimed later by garbage collection.
How often should garbage collection run in PBS?
PBS says that for most setups a weekly schedule is a good interval to start with, though the right cadence still depends on datastore behavior and workload patterns.
What does --ignore-verified mean for PBS verify jobs?
It tells PBS not to re-check backups that are already verified and not yet considered outdated. That is useful for frequent incremental verification jobs, especially when combined with a separate broader reverify rhythm.
Are verify jobs enough on their own to prove recoverability?
No. Verify jobs are essential for integrity, but they do not replace restore drills. They prove that backup data remains intact, not that your recovery process is operationally smooth.