At some point in Linux, almost everyone meets a symlink.
Maybe it looks helpful.
Maybe it looks suspicious.
Maybe it looks like a real file until you move something and suddenly the shortcut breaks and the filesystem starts teaching you a lesson you did not ask for.
That is why I think symlinks feel harder than they are.
The idea is small.
The consequences are practical.
And once those practical rules click, symlinks become one of the most useful tools in everyday Linux work.
- What a symbolic link actually is
- How `ln -s` creates one
- Why symlinks differ from hard links
- How broken links happen
- When I prefer relative links over absolute ones
A symlink is not a copy; it is a path-based reference
The symlink(7) manual page describes symbolic links as files that act as pointers to other files. The symlink(2) system call page is even more explicit: a symbolic link contains a string, and when paths are resolved, the link is interpreted as though that string were substituted into the pathname being followed.
That is the key idea.
A symlink does not contain the target file’s content.
It contains a path.
I think this is the first mental shift beginners need.
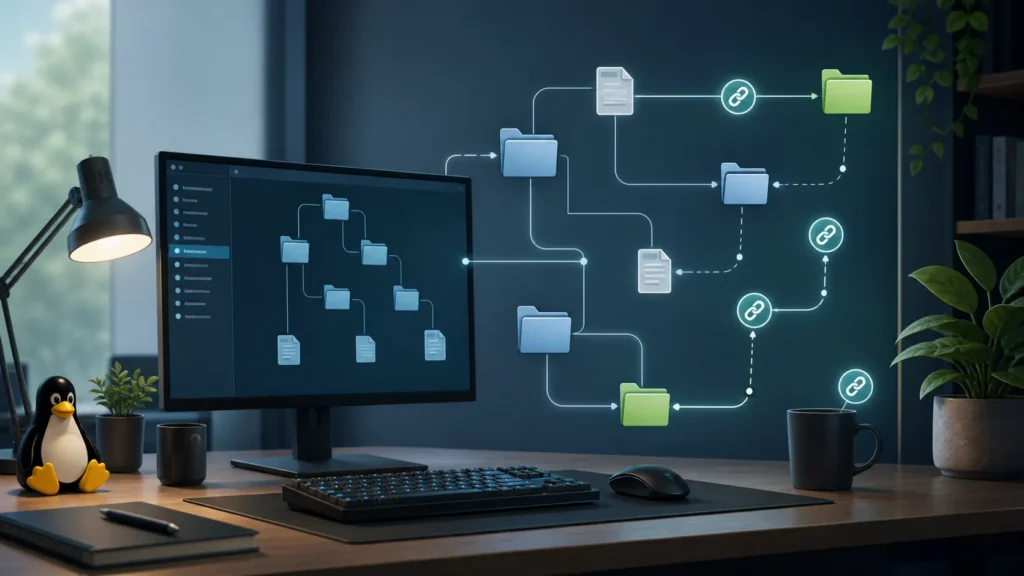
If you understand a symlink as “a special file that stores a path to somewhere else,” most of its behavior starts making sense:
- if the target exists, the link works;
- if the target moves, the path may stop working;
- if the target is deleted, the symlink does not automatically become smart enough to find it somewhere else.
That is not fragility.
That is just honesty.
ln -s is the normal way to create a symbolic link
The ln(1) manual page says hard links are created by default, and symbolic links are created with --symbolic or -s.
That means the common form is:
ln -s TARGET LINK_NAME
So if you have a real file:
/home/alex/Documents/report.txt
and you want a symbolic link to it in another location, you could do:
ln -s /home/alex/Documents/report.txt /home/alex/Desktop/report-link.txt
That creates a new file named report-link.txt which points to the path of the original report.
I think one of the most important practical details here is the order.
It is:
- target first;
- link name second.
When people are new to symlinks, they often reverse the order and end up confused about what got created where.
The biggest conceptual difference from hard links is that symlinks point by path
The symlink(7) page says you cannot really understand symbolic links without understanding hard links first, and I think that is fair. The link(2) page explains that a hard link creates a new name for the same underlying file object. The two names are simply different directory entries pointing to the same file.
That creates a huge behavioral difference:
- a hard link is another name for the same file object;
- a symlink is a separate file that stores a path to another file or directory.
The POSIX symlink(3p) application usage notes also highlight two important practical results:
- symbolic links can cross filesystem boundaries;
- hard links guarantee the underlying file continues to exist as long as a name still points to it, while symlinks do not provide that guarantee.
This is why beginners often describe symlinks as “shortcuts,” and that comparison is not terrible. It is not perfect, but it is emotionally useful. A symlink behaves much more like a path shortcut than like another real copy of the underlying file.
Broken symlinks are usually just honest evidence of a moved or missing path
Once you stop imagining symlinks as magical objects, broken links become easier to understand too.
If the symlink stores a path and that path no longer resolves, the link breaks.
That can happen because:
- the target file was deleted;
- the target was renamed;
- the target was moved somewhere else;
- a relative symlink was created from the wrong working context.
And this is where ls -l becomes your friend.
A quick listing makes the link visible:
ls -l report-link.txt
The output shows the link target after an arrow, which is often enough to reveal the problem immediately.
This is why I think symlinks reward people who read paths carefully. The link is usually not “mysteriously broken.” It is pointing exactly where it was told to point, and that place no longer matches reality.
Relative and absolute symlinks are both valid, but they age differently
This is the part that caused me the most real-world confusion.
Because symlinks store paths, you can make them with either absolute paths or relative paths.
An absolute example:
ln -s /home/alex/projects/site/config.yml current-config.yml
A relative example from inside the same project tree:
ln -s ../shared/config.yml current-config.yml
Both can be correct.
The difference is how they behave when directories move.
Absolute symlinks are often easier to reason about immediately because the target path is explicit.
Relative symlinks are often better when a whole directory tree moves together, because the relationship between the link and target can remain valid inside that moved structure.
I think the healthiest beginner rule is simple:
- use absolute paths when you want obviousness;
- use relative paths when the link is meant to travel with the surrounding directory structure.
What matters most is not ideology. It is whether the path relationship you encoded will still make sense later.
Deleting a symlink does not delete the target
This is another small but very important confidence builder.
Because a symlink is its own file, removing the symlink removes only the link, not the target it points to.
So if you run:
rm report-link.txt
you are deleting the symbolic link file, not the original report.txt.
That is one of the reasons symlinks are so useful for organizing tools, configs, or project layouts. They give you flexible access paths without duplicating content or risking the target every time you remove a reference.
The most useful beginner use cases are usually boring and practical
I think symlinks become much easier to appreciate when you stop searching for clever uses and start with ordinary ones:
- a shortcut from your home directory to a deeply nested project folder;
- a stable config path that points to the current active version;
- a shared assets directory referenced from multiple project locations;
- a more convenient command or file name in a place you visit often.
These are not glamorous.
They are just useful.
And usefulness is what helps the concept stick.
My safest symlink habit is to verify the relationship immediately
When I create a symlink, I like to do three things right away:
- create it with
ln -s; - inspect it with
ls -l; - try opening or accessing it exactly the way I expect to use it later.
That tiny verification step saves a lot of future confusion.
Because once the link exists, it is easy to assume it must be correct. But with symlinks, correctness is not about whether the file was created successfully. It is about whether the stored path resolves correctly from that link’s location and use case.
That is a very Linux kind of lesson:
the command may succeed, while the assumption behind it is still wrong.
Verification note: Commands, terminology, and support details in this guide were cross-checked against the POSIX ln utility specification.
For broader context, continue with Trying Linux Without Installing: A Guide to Live USBs and How I Run Alpine-Based LXC Containers for Ultra-Lightweight Homelab Services.
Conclusion
Linux symlinks become much easier to understand once you stop treating them like hidden copies and start treating them as path-based references. The ln -s command creates a separate file that stores a target path. If that path remains valid, the link works. If the target moves or disappears, the link breaks honestly. That is also why symlinks differ so sharply from hard links, which are additional names for the same underlying file object rather than independent pointer-like files.
That is the version of symlinks I trust most: not filesystem magic, just explicit relationships. Once you understand that a symlink is really a saved path with consequences, you can use them calmly for shortcuts, project structure, shared resources, and cleaner navigation without being surprised when paths change later.
FAQ
What is the easiest way to create a symbolic link in Linux?
Use ln -s TARGET LINK_NAME. The target path comes first, and the name of the new symlink comes second.
What is the difference between a broken symlink and a deleted file?
A broken symlink is still a real symlink file, but the path it points to no longer resolves correctly. The target may have been moved, renamed, or deleted, while the symlink itself still exists.